Blended Diffusion
CVPR 2022 reference code for text-driven local image edits: draw a mask, write a prompt, edit only that region.
Blended Diffusion is a paper and a reference implementation, not a product you can buy. If you are building a diffusion-based editor, it is worth your time: mask-plus-prompt editing with CLIP guidance and per-noise-level spatial blending is still the conceptual backbone of a lot of local editing, and the authors' augmentations to the diffusion process to mitigate adversarial results are a useful detail. If you want to edit an image this afternoon, look elsewhere. Adobe Firefly and Stable Diffusion-based inpainting UIs ship the same idea with a UI, a GPU you do not own, and someone to call when it breaks.
Verified 2d ago · liveness 39/100 · cite: rightaichoice.com/tools/blended-diffusion
- Computer vision researchers studying diffusion-based editing
- ML practitioners implementing text-guided local edits
- AI artists experimenting with diffusion models programmatically
- Developers seeding a custom image editing pipeline
- Non-technical users seeking a polished product
- Users needing real-time interaction or fast edits
- Users without access to GPU hardware
We scan live Reddit threads, YouTube comments, X posts, G2 reviews and other communities — and hand you an honest verdict in under a minute.
- Honest verdict, not marketing
- Real pros & cons from real users
- Attributed quotes with receipts
3 free scans · no card needed
Skip Blended Diffusion if you want to edit an image today through a UI rather than stand up GPU research code and draw your own mask for every edit.
You supply the GPU: running the pretrained ImageNet diffusion model plus CLIP means real compute time and hardware cost per edit, and no hosted tier absorbs it for you.
There is nothing to buy here. Blended Diffusion is published CVPR 2022 research code you host and run yourself, so the comparison is not against cheaper or pricier tiers but against hosted editing tools such as Adobe Firefly or Stable Diffusion-based inpainting UIs, where you pay a subscription and someone else pays for the GPUs. Pick this if you want the technique; pick those if you want an edit by end of day.
In short
Blended Diffusion — CVPR 2022 reference code for text-driven local image edits: draw a mask, write a prompt, edit only that region. Best for Computer vision researchers studying diffusion-based editing, ML practitioners implementing text-guided local edits, AI artists experimenting with diffusion models programmatically. Free to use.
What people actually say about Blended Diffusion — is it worth it?
We ran a structured research pass across product reviews, community discussions, and post-purchase forum threads to surface the patterns vendors won't publish themselves. Below: the recurring strengths, the hidden costs people mention most, and the cohort that consistently regrets adopting this tool.
1 mentions across 1 source (Lemmy) · researched Jul 3, 2026.
Average across the 1 source that answered — each source counts once, not each post.
- +Free and open-source—no cost to use or modify.
- +Enables natural language-guided local edits on images.
- +Preserves background fidelity via spatial blending.
- +Generates multiple plausible outputs for the same prompt.
- +Published in CVPR 2022—well-researched method.
- −Requires technical setup (local environment, dependencies).
- −No GUI; operates via command line or scripts.
- −User must manually create a mask for each edit.
- −Sparse community—few users, minimal support or tutorials.
- −Blending artifacts possible, especially at mask boundaries.
- • Compute costs for running on GPU (hardware required)
- • Setup time for dependencies
Viability Score
How well maintained and how widely used is Blended Diffusion? Built from what the vendor actually publishes (docs, changelog, tutorials, integrations, pricing), whether the site is live, and how much real users discuss it. How we calculate this
Last calculated: October 2026
How we score →Key Features
- Text-driven local editing of natural images
- Region-based edits using an ROI mask plus a text prompt
- Spatial blending of noised input image with text-guided diffusion latents across a progression of noise levels
- CLIP used to steer the diffusion process toward the prompt
- Pretrained ImageNet DDPM for generation
- No finetuning required on target images
- Add new objects to a scene from text prompts
- Remove, replace, or alter existing objects
- Background replacement from a masked background plus text description
- Image extrapolation
- Scribble-guided editing: rough shape and color reference transformed to match the prompt
- Multiple plausible synthesis results for the same text prompt
- Augmentations added to the diffusion process to mitigate adversarial results
- Inpainting behavior when no text prompt is given
- Self-hosted research code requiring a GPU
About Blended Diffusion
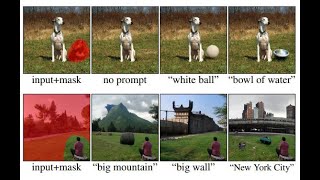
Blended Diffusion is a research implementation from the Hebrew University of Jerusalem and Reichman University, published at CVPR 2022 by Omri Avrahami, Dani Lischinski, and Ohad Fried. You give it three things: an input image, a mask you draw yourself over the region you want changed, and a short text prompt. It edits only the masked area and leaves the rest of the picture alone. Under the hood it pairs CLIP, a pretrained language-image model, to steer the edit toward your prompt with a pretrained ImageNet DDPM to generate natural-looking pixels, then spatially blends noised versions of your input image with the text-guided diffusion latent at a progression of noise levels so the edit fuses with its surroundings. It is presented as the first solution for region-based edits in generic natural images driven purely by natural language. The authors report gains over baselines on realism, background preservation, and text alignment, and demonstrate adding new objects, removing, replacing or altering existing objects, background replacement, image extrapolation, and scribble-guided editing where a rough shape and color reference is transformed to match the prompt. It runs from research code you host yourself and needs a GPU. There is no signup, hosted editor, or support desk, and the paper's project page ships PDF, arXiv, video, and code links rather than a product.
Behind the Verdict
The interesting thing about Blended Diffusion is the mechanism, not the packaging. Most text-to-image work in 2022 generated whole pictures; this paper asked a narrower and harder question — can you change one region of an existing photo and leave the other 90% of the pixels believable? The answer was to run a pretrained ImageNet DDPM under CLIP guidance, then at every noise level blend the noised input image back into the noised CLIP-generated image, and let the reverse diffusion step re-project the blend onto a cleaner manifold. The authors are explicit that each individual blend is not guaranteed to be coherent; the projection to the next manifold is what makes it cohere. That is the trick, and it is the reason the background survives an edit. Strengths, concretely: it works on generic natural images rather than a single domain; it needs no finetuning on the target image; it produces multiple plausible results for the same prompt, which matters because the problem is one-to-many by nature and you want to pick; and it handles a genuinely wide set of edit types from one interface — add, remove, replace, alter, replace the background, extrapolate. The scribble-guided mode is a nice touch: you sketch a rough shape and color, give a prompt, and the model transforms your scribble to match the text, and the authors note the scribble pattern itself can change. They even show a clip-art table being turned into a real-looking object. Weaknesses are the ones you would expect from research code. You supply the mask for every single local edit — there is no automatic segmentation step here. You need significant GPU compute and enough ML fluency to stand up the environment and drive the pipeline. There is no signup, no hosted editor, no support channel, and no product roadmap; the project page is a paper page with PDF, arXiv, video, and code. If your goal is production deployment, treat this as a technique to reimplement or borrow from rather than a service to depend on. If your goal is understanding how mask-plus-prompt editing works, read the paper and the code together — the blending schedule is the part worth stealing.
Researching Blended Diffusion? Get your full AI stack in 60 seconds.
Free, no signup — tell us your goal and get tools matched to your budget & existing stack.
Real-world workflow fit
Concrete scenarios for the personas Blended Diffusion actually fits — and what changes day-one when you adopt it.
You want to reproduce the paper's mask-plus-prompt edits and measure background preservation against a baseline. You set up the environment, run the pretrained ImageNet DDPM under CLIP guidance, and step through the per-noise-level blending schedule on your own images with hand-drawn masks.
Outcome: You get multiple plausible outputs per prompt, a concrete implementation of the blending trick to inspect, and the authors' augmentations to the diffusion process to study as a mitigation for adversarial results.
You need edit-only-the-masked-region behavior in your own product and want a reference implementation. You start from the code, keep the CLIP-guided denoising and the spatial blend of noised input with the diffusion latent, and swap in your own segmentation to remove the manual mask step.
Outcome: You ship a local edit path that preserves unmasked pixels, with the paper as the spec for the blending schedule you adapted.
You sketch a rough shape and color for an object you want to insert into a photo, mask the target area, and give a short text prompt, then generate several results for the same prompt.
Outcome: Your scribble is transformed into an object matching the prompt, with the surrounding image untouched, and you pick the variation that works.
Use Cases
- Edit a masked region of a photo by describing the desired content in text
- Add a new object such as a dog, rock, or plant while preserving the background
- Alter an existing foreground object, like changing a bowl's contents to a white ball
- Replace a masked background using a text prompt
- Generate multiple plausible variations of the same edit and pick one
- Scribble-guided insertion: sketch a rough shape and color, then give a text prompt
- Produce an inpainted result when no text prompt is supplied
- Reproduce the mask-plus-prompt and per-noise-level blending approach inside your own editing pipeline
Models Under the Hood
as of 2026-10-17
Limitations
- Blended Diffusion is a CVPR 2022 research implementation rather than a hosted product: the project page ships PDF, arXiv, video, and code links, with no signup or support channel.
- Running it requires significant GPU compute and ML expertise.
- It pairs CLIP with a pretrained ImageNet diffusion model and adds augmentations to the diffusion process to mitigate adversarial results.
- You must supply an ROI mask yourself for every local edit — there is no automatic segmentation step.
- The authors state that each individual spatial blend is not guaranteed to be coherent; coherence comes from the projection to the next noise manifold.
- The problem is one-to-many by design, so results vary across runs for the same prompt.
as of 2026-10-09
Verification history
We have re-verified Blended Diffusion 10 times since . Each pass re-reads the vendor's own pages and re-checks every listed field against that evidence; passes where nothing had changed are marked as such.
- — re-checked, vendor evidence unchanged
- — re-checked, vendor evidence unchanged
- — re-checked, vendor evidence unchanged
- — re-checked, vendor evidence unchanged
- — re-checked, vendor evidence unchanged
- — re-checked, vendor evidence unchanged
Showing the 6 most recent of 10 verification passes.
Free to cite with attribution — this page re-verifies continuously.
Where the pricing makes sense
The company stage and team size where Blended Diffusion's pricing actually pencils out — and where peers do it cheaper.
There is nothing to buy here. Blended Diffusion is published CVPR 2022 research code you host and run yourself, so the comparison is not against cheaper or pricier tiers but against hosted editing tools such as Adobe Firefly or Stable Diffusion-based inpainting UIs, where you pay a subscription and someone else pays for the GPUs. Pick this if you want the technique; pick those if you want an edit by end of day.
Setup time & first value
How long it actually takes to get something useful out of Blended Diffusion — broken out by persona, not the marketing-page minute.
Researchers and ML practitioners with a working GPU environment: expect an afternoon to a day to get the code running and produce your first mask-plus-prompt edit, since you also need CLIP and the pretrained ImageNet diffusion weights in place. AI artists and non-technical users: this is not a sign-up-and-go path — until you have the environment running, first value is effectively blocked.
Switching to or from Blended Diffusion
How to bring data in from common predecessors and how to get it back out — written for the switcher, not the buyer.
- →From manual photo editing: move the region you would have retouched into an ROI mask, describe the change in a short text prompt, and let the diffusion edit fill only that area.
- ↗To Adobe Firefly: redo the same mask-plus-prompt edit in a hosted UI when you want the result without standing up GPU code.
- ↗To a Stable Diffusion-based inpainting UI: keep the mask-plus-prompt workflow, drop the manual environment setup, and run inpainting through a product interface.
- ↗To Runway: move whole-image or masked edits into a hosted tool when you need faster turnaround than a self-hosted diffusion pipeline allows.
Resources & Guides
Tutorials & Learning
YouTube returned 6 videos for “Blended Diffusion”, and we withheld 5: 5 did not mention Blended Diffusion. Showing the 1 we can prove is about Blended Diffusion.
Official links
Tools that pair well with Blended Diffusion
Common stack mates teams adopt alongside Blended Diffusion, with the specific reason each pairing earns its keep.

Flux Kontext AI
Browser-based AI image editor that applies natural-language edits to your existing JPG or PNG using FLUX.1 Kontext Pro and Max models.
NanaImage
NanaImage (Nana Banana) is a prompt-driven AI image editor built for character consistency in AI influencer and UGC series.
Infinite Kanvas
Free AI image editor for style transfer and text-to-image on an infinite canvas
Featured Head-to-Head Comparisons
Blended Diffusion vs Adobe Firefly Services
If you are a researcher or hobbyist with a GPU and Python skills, Blended Diffusion is a powerful free tool for local text-guided image editing. But for any production, enterprise, or compliance-heavy use case, Adobe Firefly Services is the obvious choice: it offers scalable APIs, commercial safety, and deep Adobe ecosystem integration — despite costing money.
Blended Diffusion vs Qoves
For a self-improvement seeker wanting a personalized, research-backed non-surgical plan, QOVES is the clear choice despite its paid model. For a researcher or developer needing a state-of-the-art diffusion editing method to build upon, Blended Diffusion is the free, open-source tool. Pick based on your goal: personal transformation vs technical experimentation.
Blended Diffusion vs The New Black
For fashion designers needing a production-ready AI tool, The New Black is the clear winner with its high-resolution outputs, tech pack exports, and custom AI models. Blended Diffusion is a powerful research tool for developers and academics, but it lacks polish and practical integrations for commercial fashion workflows.
Alternatives to Blended Diffusion
View all
Flux Kontext AI
Browser-based AI image editor that applies natural-language edits to your existing JPG or PNG using FLUX.1 Kontext Pro and Max models.
NanaImage
NanaImage (Nana Banana) is a prompt-driven AI image editor built for character consistency in AI influencer and UGC series.
Infinite Kanvas
Free AI image editor for style transfer and text-to-image on an infinite canvas
Frequently Asked Questions
Used Blended Diffusion? Help shape our editorial sentiment research.