
fal.ai
Serverless inference API for generative image, video, audio, and 3D models with per-output pricing and no GPU management.
If your team ships generative media features and doesn't want to run GPU clusters, fal.ai is the shortest path from an idea to a billed endpoint. The catalog is broad and the rates are published per unit, so you can estimate a Kling v3 Pro 5-second clip at $0.14/sec before you commit. Recent Platform MCP and Observability APIs let you debug Serverless apps from Claude Code or Cursor instead of a status page. The catch is that this is a pay-per-output bill you have to forecast: Seedance 2 tokens, Nano Banana 2 images, and hourly H100 time all stack up, and no flat rate exists. Teams that want a free interactive sandbox before paying should test Replicate first; teams that want one
Verified 1h ago · liveness 83/100 · cite: rightaichoice.com/tools/fal-ai
- Engineering teams calling generative image, video, audio, and 3D models over one API
- Startups shipping generative media features without building or renting GPU infrastructure
- Enterprise teams that need SOC 2, SSO, private model endpoints, and usage analytics
- Research labs running large-scale training or fine-tuning on dedicated H100/H200/B200 clusters
- Non-technical users who want a point-and-click generative media studio
- Teams that need a free interactive sandbox before committing budget
- Deployments requiring on-premise or edge inference
We scan live Reddit threads, YouTube comments, X posts, G2 reviews and other communities — and hand you an honest verdict in under a minute.
- Honest verdict, not marketing
- Real pros & cons from real users
- Attributed quotes with receipts
3 free scans · no card needed
Skip fal.ai if you need a free interactive sandbox before paying or a fixed flat-rate monthly bill, rather than usage-based per-output pricing that scales with every image and video you generate.
Model API prices are per listed billing unit, so higher resolution, longer duration, or better quality settings raise the final cost above the headline rate.
fal.ai fits engineering teams comfortable with a usage-based bill: Model APIs bill per output, and Compute runs from a $2.49/hr discounted H100 rate ($4.50/hr list) up to $12.99/hr for B300. There is no free tier, so budget-conscious evaluators often test Replicate's free sandbox first, while teams that want one flat monthly rate may prefer an opinionated app over an API.
In short
fal.ai — Serverless inference API for generative image, video, audio, and 3D models with per-output pricing and no GPU management. Best for Engineering teams calling generative image, video, audio, and 3D models over one API, Startups shipping generative media features without building or renting GPU infrastructure, Enterprise teams that need SOC 2, SSO, private model endpoints, and usage analytics. Plans from $2.49.
What's new in fal.ai
Checked todayAcross the latest 4 updates: 2 feature updates, 1 launch and 1 changelog entry.
Billing headers for shared WebSocket endpoints
Shared WebSocket endpoints can declare billable units on the 101 upgrade response via x-fal-billable-units, then report totals to POST /requests/billable-units/{request_id}.
Playground testing for Serverless app endpoints
Deployed Serverless apps now show Testing > Playground in the dashboard, letting teams pick an endpoint, fill its generated input form, and run a request in place.
Serverless Observability APIs
New endpoints expose programmatic serverless app state: GET /v1/serverless/apps lists deployed apps with active runners, queue size, machine types, and environment, with expand=endpoints for route ids.
Platform MCP server for account operations
Platform API MCP server at api.fal.ai/v1/mcp/platform exposes 15 read-only, stateless tools for serverless debugging — requests, logs, analytics, deploys, runner state, spend — for Claude Code and Cursor.
What people actually say about fal.ai — is it worth it?
We ran a structured research pass across product reviews, community discussions, and post-purchase forum threads to surface the patterns vendors won't publish themselves. Below: the recurring strengths, the hidden costs people mention most, and the cohort that consistently regrets adopting this tool.
59 mentions across 5 sources (Hacker News, Product Hunt, Bluesky, GitHub, Lemmy) · researched Jul 3, 2026.
Average across the 5 sources that answered — each source counts once, not each post.
- +Access to 1,000+ models including latest like Kling 3.0.
- +Fast inference, often up to 10x faster than alternatives.
- +Serverless deployment with autoscaling from zero to thousands.
- +Free credits on signup with no credit card required.
- +MCP server support for integration with AI assistants.
- −CDN storage speed is very slow for generated media.
- −API credit policy feels restrictive and not unique.
- −Cold start latency can be noticeable for some models.
- −Pricing details are not fully transparent upfront.
- −Limited community support outside of official channels.
- • Storage and CDN costs not clearly itemized; may incur extra for media delivery.
- • GPU compute may have minimum commitment periods for dedicated instances.
Viability Score
How well maintained and how widely used is fal.ai? Built from what the vendor actually publishes (docs, changelog, tutorials, integrations, pricing), whether the site is live, and how much real users discuss it. How we calculate this
Last calculated: October 2026
How we score →Key Features
- 1,000+ generative models for image, video, audio, speech, and 3D
- Unified REST API with Python, JavaScript, and cURL SDKs
- Per-output billing for Model APIs and hourly billing for Compute
- Serverless autoscaling from zero to thousands of GPUs
- fal Inference Engine claimed up to 10x faster for diffusion models
- Dedicated GPU compute: H100, H200, B200, B300, GB200, RTX PRO 6000
- Deploy custom fal.App endpoints with setup() and @fal.endpoint methods
- Direct Server Mode for deploying Docker servers like ComfyUI
- Scaling controls: min_concurrency, max_concurrency, concurrency_buffer
- Streaming and real-time WebSocket connections on supported models
- Billing headers for shared WebSocket endpoints via x-fal-billable-units
- Serverless Observability APIs for active runners, queue size, machine types
- Platform MCP server with 15 tools for requests, logs, analytics, deploys, spend
- Playground testing for deployed Serverless app endpoints in the dashboard
- fal Agent for generating and editing image, video, audio, and 3D in one conversation
About fal.ai
fal.ai is a generative media platform for developers. You call 1,000+ production models for image, video, audio, speech, and 3D through one REST API and Python, JavaScript, or cURL SDKs, and you pay per output rather than reserving GPUs. The catalog covers Seedream 5.0, GPT Image 2.5, Flux 3, Nano Banana 2.1, Ideogram 4, Krea 2, Seedance 2.5, Kling 3.0, MiniMax H3 Max, Veo 3.1, ElevenLabs TTS, and Tripo H3.1 for 3D. Published unit prices include Seedance 2 image-to-video at $0.014 per 1,000 tokens, Kling v3 Pro image-to-video at $0.14/sec, H3 Max Turbo text-to-video at $0.025/sec, and ElevenLabs Multilingual v2 at $0.10 per 1,000 characters. Three deployment paths sit under the model gallery: Model APIs with per-output billing, Serverless for your own fal.App or Docker-based endpoints with autoscaling from zero, and Compute for dedicated H100, H200, B200, B300, GB200, and RTX PRO 6000 instances from $2.49/hr for H100 as low as. In the dashboard you get Playground testing for deployed Serverless endpoints, Observability APIs that report active runners and queue size, and a Platform MCP server with 15 tools for Claude Code and Cursor. Billing headers for shared WebSocket endpoints let you charge billable units back to the caller. It is infrastructure for engineers: there is no no-code studio, and your monthly number moves with your volume.
Behind the Verdict
fal.ai's value is the combination of model breadth and billing model. You get one API key that reaches Seedream 5.0, GPT Image 2.5, Flux 3, Kling Video v3 Pro, MiniMax H3 Max, Veo 3.1, ElevenLabs TTS, and Tripo H3.1, with a documented unit price for each. That means you can compare a $0.014-per-1,000-token Seedance 2 clip against a $0.14/sec Kling v3 Pro clip on the same bill, and the Sandbox lets you try both before you wire one into production. The second layer is Serverless: a fal.App is a Python class where setup() loads weights once per runner and @fal.endpoint methods serve requests, with min_concurrency, max_concurrency, and concurrency_buffer controlling the cost/latency tradeoff. Direct Server Mode runs Docker servers like ComfyUI without a rewrite. The third layer is Compute, where H100 list price is $4.50/hr but advertised as low as $2.49/hr, H200 as low as $2.99/hr, and B200 as low as $5.49/hr, with GB200 and B300 available for large training runs. The gaps are real. There is no free tier, so evaluating means committing a payment method and accepting variable costs. There is no point-and-click studio and no on-premise or edge option documented. Your own model deployments require Python or Docker, which is friction for non-Python stacks. And because pricing normalizes 1MP images and 5-second 720p video for comparison, higher resolutions cost proportionally more than the headline figures suggest. Treat it as infrastructure with an engineer-friendly bill, not a product with a predictable monthly rate.
Researching fal.ai? Get your full AI stack in 60 seconds.
Free, no signup — tell us your goal and get tools matched to your budget & existing stack.
Real-world workflow fit
Concrete scenarios for the personas fal.ai actually fits — and what changes day-one when you adopt it.
Pick fal-ai/nano-banana-2 in the marketplace, call it with fal_client.subscribe, and stream results to the app; use the Sandbox to compare Nano Banana 2 at $0.08/image against Flux 3 at $0.024/megapixel.
Outcome: A billed endpoint in production the same day with no GPU provisioning, and a per-image cost you can forecast from published rates.
Write a fal.App with setup() loading weights on GPU-H100, define @fal.endpoint methods, run fal run to test on a cloud GPU, then fal deploy with min_concurrency=2 and max_concurrency=100.
Outcome: Persistent autoscaling endpoint with revision rollbacks, real-time logs, and Prometheus metrics or log drains to an existing observability stack.
Provision H200 or B200 instances through Compute for a large training run, then serve the resulting model on Serverless for inference with the same API key.
Outcome: One vendor for training and serving, with hourly GPU rates ($6.00/hr H200 list, $2.99/hr as low as) that you can reconcile against usage analytics.
Use Cases
- Ship real-time image generation into a social or design product via one API call
- Add text-to-video or image-to-video features to a marketing tool without owning GPUs
- Deploy a fine-tuned model on Serverless and let it autoscale from zero to thousands of GPUs
- Run speech and audio generation for voice features in a support or media product
- Power generative media inside an existing SaaS app with per-output billing
- Deploy an existing Docker server like ComfyUI through Direct Server Mode without rewriting code
- Train or fine-tune custom models on dedicated H100, H200, or B200 clusters
- Compare image and video models side-by-side in the Sandbox before committing to one
Models Under the Hood
as of 2026-09-26
Limitations
- Pricing is billed per output — per second or per video for video models, per image or megapixel for image models, hourly for Compute — so your monthly bill scales directly with app usage and model choice, and a runaway app converts straight into a runaway invoice.
- Dedicated GPU instances may carry minimum commitments, and the fleet is limited to the listed NVIDIA hardware across available regions.
- Deploying your own model requires writing fal.App Python code or bringing a Docker server, so non-Python and non-Docker stacks have more friction.
- There is no no-code studio, and no on-premise or edge option is documented.
- Pricing on the site is normalized for comparison (1MP images, 5-second 720p video), so real output at higher resolutions costs proportionally more than the headline figures suggest.
as of 2026-10-09
Verification history
We have re-verified fal.ai 9 times since . Each pass re-reads the vendor's own pages and re-checks every listed field against that evidence; passes where nothing had changed are marked as such.
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-checked, vendor evidence unchanged
Showing the 6 most recent of 9 verification passes.
Free to cite with attribution — this page re-verifies continuously.
12-month cost
Project the real annual outlay, including the implied monthly cost when only an annual tier is published.
Vendor list price only. Add-on usage, seat overages, and contract minimums are surfaced under Hidden costs & gotchas.
Plans compared
For each published fal.ai tier: who it actually fits, and what it adds vs. the previous tier. Cross-reference the cost calculator above for projected annual outlay.
Model APIs (per-output)
Pay-per-output
Ideal for
Developers and product teams adding image, video, audio, or 3D generation to an app who want to pay only for what they use.
What this tier adds
Starting tier — per-output billing with published unit prices, e.g. Seedance 2 image-to-video at $0.014/1,000 tokens and Nano Banana 2 at $0.08/image.
Compute (dedicated GPUs)
From $2.49/hr (H100, discounted)
Ideal for
Research labs and platform teams running training, fine-tuning, or persistent workloads that need dedicated NVIDIA hardware.
What this tier adds
Adds hourly dedicated instances from $2.49/hr discounted H100 (list $4.50/hr) up to $12.99/hr B300, with guaranteed-capacity options and custom deployment via support@fal.ai.
Where the pricing makes sense
The company stage and team size where fal.ai's pricing actually pencils out — and where peers do it cheaper.
fal.ai fits engineering teams comfortable with a usage-based bill: Model APIs bill per output, and Compute runs from a $2.49/hr discounted H100 rate ($4.50/hr list) up to $12.99/hr for B300. There is no free tier, so budget-conscious evaluators often test Replicate's free sandbox first, while teams that want one flat monthly rate may prefer an opinionated app over an API.
Setup time & first value
How long it actually takes to get something useful out of fal.ai — broken out by persona, not the marketing-page minute.
For Model APIs: minutes — the quickstart is three lines of code (fal_client.subscribe with your FAL_KEY). For Serverless: hours — you need a fal.App Python class or a Docker server, then fal run to test and fal deploy to productionize. For Compute: faster than provisioning your own region, but plan for the credit and commitment conversation with support@fal.ai.
Switching to or from fal.ai
How to bring data in from common predecessors and how to get it back out — written for the switcher, not the buyer.
- →From a self-hosted diffusion stack: port your model to a fal.App with setup() and @fal.endpoint, or run ComfyUI via Direct Server Mode without a rewrite.
- →From Replicate: swap the HTTP client for fal_client.subscribe and move to fal-ai/* model IDs, then compare published per-unit prices for the same models.
- →From a raw GPU cloud: keep the training workload on Compute and move only inference to Serverless so you stop paying for idle GPU hours.
- →From scattered vendor APIs: consolidate image, video, audio, and 3D calls under one fal key and one usage dashboard.
- ↗To Replicate: re-point model IDs and expect a free sandbox for evaluation, at the cost of fewer dedicated GPU options.
- ↗To a hyperscaler AI platform: port fal.App endpoints to containers and reproduce autoscaling yourself, typically with more infrastructure work.
- ↗To a no-code media studio: keep the model outputs but hand generation to non-technical teammates, losing per-call API control.
Integrations
Resources & Guides
Tutorials & Learning
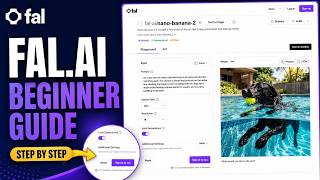
YouTube returned 6 videos for “fal.ai”, and we withheld 5: 5 could not be judged, because “fal.ai” is a single word that other videos use for other things. Showing the 1 we can prove is about fal.ai.
Official links
Tools that pair well with fal.ai
Common stack mates teams adopt alongside fal.ai, with the specific reason each pairing earns its keep.
WaveSpeedAI
Pay-per-use API and desktop app for AI image, video, audio, 3D and LLM generation across 1000+ models.
Pollinations
One free REST API for text, image, audio, and video generation — no API key required
MimicPC
Browser-based cloud that runs 20+ pre-installed open-source AI apps for image, video, and audio generation
Featured Head-to-Head Comparisons
Fal Ai vs Spider Cloud
For AI application developers building generative media features, fal.ai is the clear choice with its vast model library and high-speed inference. If you need real-time web data for AI agents or RAG pipelines, Spider Cloud's crawling and scraping API is purpose-built and cost-effective. Choose based on your data source: generated content (fal) vs. web content (Spider).
Fal Ai vs Temporal Ai
If you need to orchestrate multi-step AI agents that survive crashes and require human oversight, choose Temporal. If you want to run 1,000+ generative models at blazing speed with minimal latency, choose fal.ai. Both serve different needs: reliability vs speed.
Fal Ai vs Voyage Ai
Voyage AI is the clear choice if your primary need is high-accuracy retrieval for domain-specific RAG, especially in regulated industries like finance or healthcare. fal.ai wins if you're building generative media applications and need fast, scalable inference on thousands of models. Choose based on your core workload: retrieval vs. generation.
Alternatives to fal.ai
View all
WaveSpeedAI
Pay-per-use API and desktop app for AI image, video, audio, 3D and LLM generation across 1000+ models.
Pollinations
One free REST API for text, image, audio, and video generation — no API key required
Frequently Asked Questions
Categories
Best-of guides
Used fal.ai? Help shape our editorial sentiment research.