AssemblyAI
Voice AI infrastructure for developers: speech-to-text, speech understanding, guardrails, and LLM routing on one API key.
Shortlist AssemblyAI first if your roadmap includes voice agents, dictation, or call analytics. The Dictation API (launched September 2026) and Universal-3.5 Pro's native code-switching across 18 languages at $0.21/hr pay-as-you-go are the pieces competitors are still catching up on, and the Voice Agent API removes the STT-LLM-TTS glue work you would otherwise build. Compare against Deepgram if raw streaming latency is the only metric you care about, and against OpenAI's Whisper-family APIs if you want transcription bundled into an existing model contract. Skip it for bulk plain transcription where understanding, guardrails, and agents add nothing you will use.
Verified 9d ago · liveness 95/100 · cite: rightaichoice.com/tools/assemblyai
- Developers building production voice agents
- Product teams shipping dictation features
- AI notetaker and scribe teams needing low-latency transcription
- Call analytics pipelines needing speaker ID, sentiment, and summaries from one vendor
- Non-technical users who want a no-code transcription interface
- Buyers who need a finished end-user product rather than an API to build on
- High-volume plain transcription where understanding and guardrails add no value
We scan live Reddit threads, YouTube comments, X posts, G2 reviews and other communities — and hand you an honest verdict in under a minute.
- Honest verdict, not marketing
- Real pros & cons from real users
- Attributed quotes with receipts
3 free scans · no card needed
Skip AssemblyAI if you need a no-code transcription app or you are running bulk plain transcription at a volume where the understanding, guardrails, and agent layers add cost you will never use.
Universal-3.5 Pro is metered at $0.21/hr of audio, so a pipeline that re-runs transcriptions for QA or model comparison pays twice for the same recording.
Pay-as-you-go at $0.21/hr for Universal-3.5 Pro fits seed-to-Series-B product teams that want usage-metered cost without a contract, and the free starting tier lets you validate before spending. It is not a flat seat price — cost tracks audio hours, so heavy batch transcription gets expensive fast at scale. Enterprise adds custom rate limits and Self Hosted Voice AI Cloud under negotiated pricing, which is where teams with compliance requirements end up.
In short
AssemblyAI — Voice AI infrastructure for developers: speech-to-text, speech understanding, guardrails, and LLM routing on one API key. Best for Developers building production voice agents, Product teams shipping dictation features, AI notetaker and scribe teams needing low-latency transcription. Free to start; paid plans from $0.21.
What's new in AssemblyAI
Checked 9 days agoAcross the latest 5 updates: 4 feature updates and 1 launch.
LLM Gateway Models: NVIDIA Nemotron, DeepSeek v4.1 Flash, GLM 5.3, & GLM 5.3 Flash
Four new models went live on the LLM Gateway: NVIDIA's Nemotron models, DeepSeek's v4.1 Flash, and Zhipu AI's GLM 5.3 and GLM 5.3 Flash, all switchable via the model parameter.
Dictation API
AssemblyAI lists the Dictation API as its latest release, positioned as the first API built for dictation. It returns text ready to send with filler words removed and self-corrections resolved.
Gemini 3.8 Flash Now Available on the LLM Gateway
Google's gemini-3.8-flash is now available through the LLM Gateway, with a 1M-token context window and support for tool calling, structured outputs, streaming, and prompt caching.
Kimi K3 Now Available on the LLM Gateway
Moonshot AI's kimi-k3 is served through Fireworks, a new provider on the gateway, with a 1.04M-token context window and reasoning_effort control.
Introducing Qwen3.5 4B on LLM Gateway—optimized by AssemblyAI
AssemblyAI added Qwen3.5 4B to its LLM Gateway, tuned specifically for the fast rewrite tasks used in voice products.
What people actually say about AssemblyAI — is it worth it?
We ran a structured research pass across product reviews, community discussions, and post-purchase forum threads to surface the patterns vendors won't publish themselves. Below: the recurring strengths, the hidden costs people mention most, and the cohort that consistently regrets adopting this tool.
76 mentions across 5 sources (Hacker News, YouTube, Product Hunt, Bluesky, Lemmy) · researched Jul 25, 2026.
Average across the 5 sources that answered — each source counts once, not each post.
- +Streaming model with Context Carryover improves real-time conversation understanding.
- +Unified API stack: STT, Speech Understanding, Guardrails, LLM Gateway, Voice Agent.
- +Low-latency real-time WebSocket streaming praised for voice agent use cases.
- +No concurrency limits or throttles on pay-as-you-go plans.
- +Guardrails for inline PII redaction and content moderation.
- −Speechmatics and Deepgram sometimes faster for real-time streaming.
- −Top accuracy model covers only 18 languages, limiting global use.
- −Limited free tier may discourage hobbyist experimentation.
- −Community buzz is niche; less mainstream adoption than competitors.
- −Past accuracy issues mentioned despite newer models.
- • No hidden costs reported; pricing is transparent per hour of audio. However, additional APIs (Guardrails, LLM Gateway) may incur separate usage fees not detailed on the pricing page.
Viability Score
How well maintained and how widely used is AssemblyAI? Built from what the vendor actually publishes (docs, changelog, tutorials, integrations, pricing), whether the site is live, and how much real users discuss it. How we calculate this
Last calculated: October 2026
How we score →Key Features
- Pre-recorded Speech-to-Text API across 99 languages
- Realtime Speech-to-Text over WebSocket at roughly 150ms p50 latency
- Sync Speech-to-Text API returning a transcript in one HTTP request
- Sync API handles short clips up to 120 seconds with no polling
- Dictation API that strips filler words and resolves self-corrections
- Voice Agent API with managed STT, LLM reasoning, and TTS in one connection
- Voice Agent API at roughly one second end-to-end latency
- Speech Understanding API for summarization, sentiment, and topic detection
- Guardrails API for PII handling and content moderation
- LLM Gateway giving unified access to frontier language models
- Universal-3.5 Pro model with native code-switching in 18 languages
- Speaker diarization and word-level timestamps
- Keyterms prompting and custom spelling for domain vocabulary
- Python and TypeScript SDKs plus raw HTTP and WebSocket APIs
- AssemblyAI MCP Server for Claude Code, Cursor, and MCP-compatible agents
About AssemblyAI
AssemblyAI is a developer platform for voice AI, sold as APIs rather than an end-user app. Its platform splits into four layers. Transcribe covers a Pre-recorded Speech-to-Text API (asynchronous, 99 languages, speaker diarization, PII redaction), a Realtime Speech-to-Text API over WebSocket with roughly 150ms p50 latency, and a Sync Speech-to-Text API that returns a finished transcript in a single request-response call for clips up to 120 seconds. Understand covers the Speech Understanding API (summaries, sentiment, topic detection, chapters) plus Guardrails for PII handling and content moderation. Interact covers the Voice Agent API, a managed speech-to-speech pipeline that handles STT, LLM reasoning, and TTS over one connection at roughly one second end-to-end latency, and the newer Dictation API, which returns text ready to send — filler words removed, self-corrections resolved, names spelled correctly. Inference covers the LLM Gateway, a single endpoint routing to frontier models including Gemini 3.8 Flash (1M-token context window), Kimi K3, DeepSeek v4.1 Flash, GLM 5.3, and NVIDIA's Nemotron line, plus Qwen3.5 4B tuned for voice rewrite tasks. The flagship transcription model, Universal-3.5 Pro, runs at $0.21/hr on pay-as-you-go, handles 18 languages with native code-switching, and ships with the platform's most accurate speaker diarization. You can build against raw HTTP/WebSocket, a Python or TypeScript SDK, or wire it into Claude Code and Cursor via an MCP server. Start free, pay as you go after that.
Behind the Verdict
AssemblyAI's pitch is breadth on one API key, and the current platform backs it up. The transcribe layer gives you three distinct products for three real problems: Pre-recorded for asynchronous batch audio across 99 languages, Realtime over WebSocket at roughly 150ms p50 latency for live captions and agent assist, and Sync for short clips up to 120 seconds where a polling loop is pointless. That last one matters more than it sounds — most dictation features in web apps live in that 120-second window, and a single request-response call is far less code than webhooks and job status checks. The Dictation API, launched in September 2026, is the sharpest differentiator. It does not just transcribe; it returns text ready to send, with filler words stripped, self-corrections resolved, and names spelled correctly. If you are building a notetaker or an in-app dictation field, that post-processing is work you would otherwise own — and assembly is the kind of post-processing that quietly breaks when you do it yourself with regex. The understanding layer is where the platform earns its keep for analytics use cases. Speech Understanding gives you summarization, sentiment, and topic detection on top of transcripts; Guardrails handles PII redaction and content moderation so you can govern what audio data flows through the pipeline. For call analytics and compliance, getting speaker ID, sentiment, and redaction from one vendor is meaningfully less integration surface than stitching three. The LLM Gateway is the quiet workhorse. Gemini 3.8 Flash, Kimi K3, DeepSeek v4.1 Flash, GLM 5.3, NVIDIA's Nemotron models, and Qwen3.5 4B tuned specifically for voice rewrite tasks all sit behind the same API as your transcription calls. That means the reasoning step in a voice product does not require a second vendor contract, a second key, and a second billing relationship. Where it gets weaker: cost transparency past the pay-as-you-go rate. Universal-3.5 Pro at $0.21/hr is a clean number, but custom rate limits, volume pricing, and the Self Hosted Voice AI Cloud all route through contact-sales, which means you cannot price a large deployment without a conversation. The Sync API also has a real ceiling — clips up to 120 seconds — so long-form audio must go through the async path. And the platform is API-only; there is no end-user transcription app here, so non-technical buyers are in the wrong place. The fit is narrow but deep: product teams with engineers on staff who are building voice into something else. If that is you, AssemblyAI collapses a lot of vendor management into one integration.
Researching AssemblyAI? Get your full AI stack in 60 seconds.
Free, no signup — tell us your goal and get tools matched to your budget & existing stack.
Real-world workflow fit
Concrete scenarios for the personas AssemblyAI actually fits — and what changes day-one when you adopt it.
You call the Dictation API with recorded audio from the browser, receive text with filler words stripped and self-corrections resolved, and drop it straight into the input field without a post-processing pass.
Outcome: Sendable text on the first call, with no LLM cleanup step or regex layer to maintain.
You send recorded calls to the Pre-recorded Speech-to-Text API with diarization enabled, run Speech Understanding for sentiment and topics, and apply Guardrails to redact PII before anything lands in your warehouse.
Outcome: Speaker-attributed, redacted transcripts with sentiment and topic labels from one vendor instead of three.
You open one Voice Agent API connection and let AssemblyAI own the STT, LLM reasoning, and TTS loop, then swap the reasoning model through the LLM Gateway when you want to test Gemini 3.8 Flash against Qwen3.5 4B.
Outcome: A working speech-to-speech agent at roughly one second end-to-end latency without assembling a pipeline yourself.
Use Cases
- Building AI notetakers that need high-accuracy transcription with speaker diarization
- Shipping in-app dictation fields that return sendable text instead of raw transcripts
- Running voice agents for customer support with managed turn detection and interruption handling
- Analyzing call center recordings for sentiment, topics, and compliance redaction
- Building clinical dictation workflows with a guide AssemblyAI publishes for that use case
- Creating searchable podcast archives with word-level timestamps and speaker labels
- Real-time captioning for live events over the Realtime API
- Routing post-transcription reasoning through one LLM Gateway instead of separate model contracts
Models Under the Hood
as of 2026-09-15
Limitations
- The Sync API only covers clips up to 120 seconds, so anything longer has to go through the asynchronous Pre-recorded path.
- Pricing past the pay-as-you-go rate is not self-serve: custom rate limits, volume discounts, and the Self Hosted Voice AI Cloud all route through contact sales, so you cannot size a large deployment from the pricing page alone.
- Self-hosting is an enterprise arrangement rather than an option small teams can take.
- The platform is APIs and SDKs with no end-user app, which means you need engineering capacity to get anything out of it.
- Guardrails handles PII and moderation, but you remain responsible for how you configure redaction across your own pipeline.
as of 2026-09-29
Verification history
We have re-verified AssemblyAI 20 times since . Each pass re-reads the vendor's own pages and re-checks every listed field against that evidence; passes where nothing had changed are marked as such.
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
- — re-verified summary, description, our verdict, our analysis, pricing model, pricing tiers, features, integrations, who it suits, who should skip it
Showing the 6 most recent of 20 verification passes.
Free to cite with attribution — this page re-verifies continuously.
12-month cost
Project the real annual outlay, including the implied monthly cost when only an annual tier is published.
Vendor list price only. Add-on usage, seat overages, and contract minimums are surfaced under Hidden costs & gotchas.
Plans compared
For each published AssemblyAI tier: who it actually fits, and what it adds vs. the previous tier. Cross-reference the cost calculator above for projected annual outlay.
Free
$0
Ideal for
Solo developer or small team validating transcription accuracy on real audio before committing budget.
What this tier adds
Starting tier: API access with no commitment, including the Playground, language detection, formatting, and word-level timestamps.
Pay-as-you-go
$0.21/hr
Ideal for
Product teams in production who want usage-metered cost with no contract and no concurrency ceiling.
What this tier adds
Adds Universal-3.5 Pro at $0.21/hr, 18-language code-switching, speaker diarization, and keyterms prompting with no concurrency limits.
Enterprise
Custom
Ideal for
Organizations with compliance review, custom volume, or a requirement to run the Voice AI Cloud in their own environment.
What this tier adds
Adds custom rate limits, Self Hosted Voice AI Cloud, volume pricing, and dedicated support and onboarding.
Where the pricing makes sense
The company stage and team size where AssemblyAI's pricing actually pencils out — and where peers do it cheaper.
Pay-as-you-go at $0.21/hr for Universal-3.5 Pro fits seed-to-Series-B product teams that want usage-metered cost without a contract, and the free starting tier lets you validate before spending. It is not a flat seat price — cost tracks audio hours, so heavy batch transcription gets expensive fast at scale. Enterprise adds custom rate limits and Self Hosted Voice AI Cloud under negotiated pricing, which is where teams with compliance requirements end up.
Setup time & first value
How long it actually takes to get something useful out of AssemblyAI — broken out by persona, not the marketing-page minute.
A developer with an API key gets a first Pre-recorded transcription back in under 15 minutes using the Python SDK quickstart. Realtime is a longer session — expect half a day to wire the WebSocket client and handle turn events. Voice Agent API takes roughly a day to reach a usable loop, since you also need to pick a reasoning model through the LLM Gateway. Non-developers should budget for
Switching to or from AssemblyAI
How to bring data in from common predecessors and how to get it back out — written for the switcher, not the buyer.
- →From OpenAI Whisper: swap the transcription call for the Pre-recorded API and gain diarization, word-level timestamps, and keyterms prompting in the same request.
- →From Deepgram: move the realtime WebSocket client onto the StreamingClient SDK and reuse your existing audio frame pipeline.
- →From a self-hosted Whisper deployment: point your post-processing and storage layers at the Pre-recorded API to drop GPU maintenance.
- →From a transcription-plus-LLM DIY stack: replace the separate cleanup model with the Dictation API's filler removal and self-correction handling.
- ↗To Deepgram: rebuild realtime streaming against its WebSocket interface if its latency profile fits your workload better.
- ↗To a self-hosted Whisper deployment: move transcription on-prem if you need fully offline processing.
- ↗To OpenAI's audio APIs: consolidate onto one model contract if you are already committed to that vendor for reasoning.
- ↗To a no-code transcription tool: export existing audio and reprocess it through a GUI product if your team has no engineers.
Integrations
Resources & Guides
- Documentationassemblyai.com
AssemblyAI Documentation
Build with our Voice AI Infrastructure.
- Documentationassemblyai.com
Overview
AssemblyAI provides production-ready Voice AI models for speech-to-text, speaker detection, sentiment analysis, and more. Build with pre-recorded or streaming audio using REST APIs and WebSockets.
- Documentationassemblyai.com
End-to-end examples
Runnable end-to-end examples that combine Speech-to-Text, Speech Understanding, and LLM Gateway into complete pipelines for meetings, sales calls, medical scribes, content repurposing, and real-time streaming.
- Resourceassemblyai.com
Speech & Text | Blog from AssemblyAI
Helpful link from assemblyai.com
- Resourceassemblyai.com
Changelog
Helpful link from assemblyai.com
- Resourceassemblyai.com
Get Help
Chat with Joey, AssemblyAI
- Resourceassemblyai.com
Contact Support
Get help from the AssemblyAI support team. Complete the form to create a support ticket, or log in to live chat.
- Resourceassemblyai.com
Playground
With AssemblyAI's industry-leading Speech AI models, transcribe speech to text and extract insights from your voice data.
Tutorials & Learning
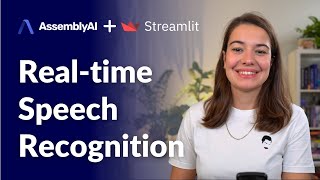
YouTube returned 6 videos for “AssemblyAI”, and we withheld 5: 5 could not be judged, because “AssemblyAI” is a single word that other videos use for other things. Showing the 1 we can prove is about AssemblyAI.
Official links
Tools that pair well with AssemblyAI
Common stack mates teams adopt alongside AssemblyAI, with the specific reason each pairing earns its keep.
Whisper Memos
Apple-only AI voice recorder that emails you formatted transcripts and routes memos to your tools by name.

Voicenotes
Voicenotes is a bot-free AI notetaker that records meetings from your own device, then hands you a summary and action items before you hang up.
Krisp Voice AI
Real-time noise cancellation, accent conversion and AI meeting notes in one app
Featured Head-to-Head Comparisons
Assemblyai vs Deepgram
Assemblyai vs Elevenlabs
If you need lifelike voice generation for content or voice agents, ElevenLabs is the pick — it excels at TTS, dubbing, and audio creation. If your core need is accurate speech-to-text and building voice AI products, AssemblyAI's APIs are what you want — especially with Universal-3.5 Pro's human-parity accuracy. Choose based on your primary input (text-to-speech vs. speech-to-text) and whether you prefer a broad creative suite or a focused developer platform.
Assemblyai vs Whisper
Assemblyai vs Voice Recorder Notes Pro
If you're a non-technical user who just needs a mobile recorder that transcribes on the go, Voice Recorder & Notes Pro's free tier and simplicity win. For developers or teams building custom voice applications—like voice agents or call analytics—AssemblyAI's API-driven platform with human-level accuracy and versatile SDKs is the clear choice. These tools serve fundamentally different needs.
Assemblyai vs Najva
Choose Najva if you're a solo macOS user needing free, offline dictation and privacy. Choose AssemblyAI if you're a developer building scalable voice applications requiring real-time streaming, 99-language support, and advanced speech understanding — AssemblyAI is a production-ready API platform, not a desktop app. There's no direct overlap; pick based on your deployment needs: local vs. cloud, free vs. pay-per-use.
Assemblyai vs Openwhispr
If you need private, offline dictation with local AI and maximum control over your data, OpenWhispr is the clear choice. If you're building voice agents, real-time transcription APIs, or speech understanding pipelines and need cloud-scale accuracy that now meets human parity, AssemblyAI is the superior platform. OpenWhispr is for the privacy-first professional; AssemblyAI is for the developer shipping voice AI.
Assemblyai vs Bitdynamic
If you need instant hands-free translation on your smart earphones or glasses and want a wearable-first assistant for calls and meetings, choose BitDynamic. If you're a developer building a voice agent, transcription pipeline, or speech understanding app with API flexibility and human-parity accuracy, AssemblyAI is the clear pick. These tools serve completely different users—wearable consumers vs. API builders—so your decision hinges on whether you need a ready-to-use app or a customizable backend.
Assemblyai vs Voicepal
If you're a solo creator who wants to bypass writer's block by speaking drafts into a mobile app, VoicePal is your tool. If you're a developer building a voice AI product that needs human-parity transcription, real-time streaming, or a voice agent API, AssemblyAI is the clear choice. They solve completely different problems, so pick based on whether you need a content creation assistant or an API platform.
Assemblyai vs Vavus Ai
If you’re an end user who needs to translate speech/text across 200+ languages, preserve your tone, and remove filler words — all in one app — go with Vavus AI. If you’re a developer building voice agents or speech-to-text pipelines that require industry-leading accuracy (human parity on Coval) and low latency (~134 ms Sync API), choose AssemblyAI. They serve fundamentally different use cases.
Alternatives to AssemblyAI
View all
Whisper Memos
Apple-only AI voice recorder that emails you formatted transcripts and routes memos to your tools by name.

Voicenotes
Voicenotes is a bot-free AI notetaker that records meetings from your own device, then hands you a summary and action items before you hang up.
Krisp Voice AI
Real-time noise cancellation, accent conversion and AI meeting notes in one app
Frequently Asked Questions
Best-of guides
Used AssemblyAI? Help shape our editorial sentiment research.